> For the complete documentation index, see [llms.txt](https://docs.imerit.net/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://docs.imerit.net/core-concepts/workflow/consensus.md).
# Consensus
A Consensus stage is a way for you to present tasks to multiple annotators, and have the task be output in either *Agreement* or *Disagreement* conditional upon how much the annotators agree with one another.
{% hint style="warning" %}
Because of the way the Consensus mechanism works under the hood, logic stages of the type "Annotator" and "Duration" may not work as expected when processing tasks output from a Consensus stage.
Requeuing tasks with issues which have been output from a Consensus stage might lead to unexpected behavior regarding the issues. We recommend closing all issues on such tasks before requeuing them.
{% endhint %}
Essentially, the Consensus stage is a container for other Label or Plugin sub-stages.
The Consensus stage accepts plugin sub-stages, such that, for example, you can have a task be labeled by an annotator and a plugin, and you may return the task based on how similarly the annotator labeled the task compared to the plugin.
There is a limit of ten maximum sub-stages you may add to the Consensus stage.
{% hint style="warning" %}
The Consensus stage, by default, does *not* prevent the same task from being labeled by the same person. To prevent that from happening, you will have to assign different annotators to different label stages, as mentioned in [the section for the Label stage](https://docs.imerit.net/core-concepts/workflow/label.md). This can be done automatically by clicking on [*Assign members automatically*](#assign-members-automatically) in the consensus stage’s *Setup* tab.
More details in the section for [Assign members automatically](#assign-members-automatically).
{% endhint %}
## Supported asset and annotation types
Built-in consensus has two separate levels of compatibility:
* **Asset-level classifications** can be scored on every standard Ango Hub asset type, as long as the classification is top-level, is not frame-specific, and does not have **Multiple Question** enabled.
* **Region, object, or span tools** are only scored when the asset is not treated as potentially multi-page or sequence-like. Ango Hub intentionally skips tool scoring on video, PDF, TIFF, DICOM, NRRD, NIfTI, and bundled multi-file assets, regardless of the actual number of pages, frames, or slices.
This means a Consensus stage may still route a video or DICOM task using a global Radio answer, for example, but it cannot use the task's frame-level or slice-level annotations to decide Agreement or Disagreement.
### Asset compatibility
| Asset type | Built-in consensus support | What can be scored |
| --------------------------------------------------------------------------------------------------------------------------------------------------------------------- | -------------------------- | -------------------------------------------------------------------------------------------------------------------------------- |
| Single image (`.jpg`, `.jpeg`, `.png`, `.bmp`, `.webp`) | **Supported** | Supported classifications, Bounding Box, Polygon, and Point annotations. |
| Audio (`.mp3`, `.wav`, `.ogg`) | **Supported** | Supported classifications and Entity annotations. |
| Text (`.txt`) | **Supported** | Supported classifications and Entity annotations. |
| Markdown | **Partially supported** | Supported classifications only. |
| LLM tasks | **Partially supported** | Supported classifications only. Message annotations are not scored. |
| Video (`.mp4`, `.webm`, `.mov`, `.mkv`) | **Partially supported** | Asset-level classifications only. Video annotations and frame-specific classifications are not scored. |
| PDF (`.pdf`) | **Partially supported** | Asset-level classifications only. PDF region annotations are not scored. |
| TIFF (`.tif`, `.tiff`) | **Partially supported** | Asset-level classifications only, even when the TIFF contains a single page. |
| DICOM (`.dcm`) | **Partially supported** | Asset-level classifications only. The built-in algorithm does not provide reliable frame-, instance-, or slice-aware comparison. |
| Medical volumes (`.nrrd`, `.nii`, `.nii.gz`) | **Partially supported** | Asset-level classifications only. Region and voxel annotations are not scored. |
| Bundled assets containing multiple files, including image grids and carousels | **Partially supported** | Asset-level classifications only. Annotations on individual files or pages are not scored. |
| [3D Multi-Sensor Fusion Tool projects](https://docs.imerit.net/3d-multi-sensor-fusion/feature-availability-status-for-projects-of-the-3d-multi-sensor-fusion-type.md) | **Not supported** | Do not connect 3D MSFT tasks to a Consensus stage. |
{% hint style="warning" %}
For partially supported asset types, only use Consensus when asset-level classifications are sufficient for your routing decision. If Agreement or Disagreement must depend on frame-, page-, slice-, or file-specific annotations, built-in consensus is not suitable.
{% endhint %}
### Annotation compatibility
| Annotation type | Consensus support | Comparison method |
| ----------------------------------------------------------------------------------------------------------- | -------------------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Tools** | | |
| Bounding Box | **Supported on eligible assets** | Intersection over Union (IoU). |
| Polygon | **Supported on eligible assets** | Intersection over Union (IoU). |
| Entity | **Supported on eligible assets** | Overlap between text spans. |
| Point | **Supported on eligible assets** | Distance between points relative to the asset diagonal. |
| Rotated Bounding Box, Polyline, Segmentation, Brush, Voxel Brush, Circle, PDF, Message, Angle, and Skeleton | **Not supported** | No built-in score is calculated. |
| **Classifications** | | |
| Radio, Checkbox, Boolean, Single-Select Dropdown, and Single-Select Tree | **Supported** | Exact answer match, subject to the [empty and zero-value limitations](#classifications). |
| Multi-Select Dropdown and Multi-Select Tree | **Supported** | Intersection over union of the selected answer sets. |
| Text and Slider | **Supported** | Exact answer match, subject to the [empty and zero-value limitations](#classifications). Text comparison is case-sensitive and includes whitespace. |
| File Upload Box | **Technically supported** | Exact URL match. Separately uploaded files normally have different URLs, so this is rarely useful for consensus. |
| Classifications with **Multiple Question** enabled | **Not supported** | Repeatable classifications are excluded from scoring. This is different from a Multi-Select Dropdown or Tree, which is supported. |
| Frame-specific classifications | **Not supported** | Excluded from scoring. |
| Nested classifications | **Not scored independently** | They are carried with their selected parent answer during adjudication. |
| **Relations** | | |
| Single Relation and Group Relation | **Not supported** | Relations are not scored or copied to the adjudicated output. |
{% hint style="info" %}
The built-in consensus score calculation supports a limited set of annotation tools and modalities. If your project requires broader support, including video annotations, rotated bounding boxes, polylines, segmentation, brush, voxel brush, or Message annotations, you can use a **Consensus** stage together with the **Calculate Consensus Score** plugin. For setup instructions and the plugin's compatibility list, see [the Calculate Consensus Score documentation](https://docs.imerit.net/plugins/first-party-ango-plugins/calculate-consensus-score.md).
{% endhint %}
## How Consensus processes a task
When a task reaches a Consensus stage, Ango Hub performs the following steps:
1. The original task remains at the Consensus stage while Ango Hub creates one copy, called a *sub-task*, for every Label or Plugin sub-stage inside the container.
2. Each copy is placed in its own sub-stage queue. Labelers or plugins complete the copies independently.
3. Every submitted copy is saved in the original task's Stage History and moved to Archive. The original task does not continue until all copies from the current consensus iteration have been submitted.
4. Ango Hub determines which classifications and tools are eligible for scoring, based on the [asset and annotation compatibility rules](#supported-asset-and-annotation-types).
5. For every eligible class, Ango Hub compares every submitted answer with every other answer, including itself. It produces a score for each submission and a final score for the class.
6. Ango Hub checks each numeric final class score against its enabled threshold. A score below its threshold sends the task through *Disagreement*; otherwise, it leaves through *Agreement*. Classes without a numeric score are skipped.
7. Separately from routing, Ango Hub applies the selected adjudication method to build the answer passed to the next stage.
8. The original task continues through the selected output, and the individual submissions remain available in Stage History.
You may examine individual sub-tasks and check their current status from the "Tasks" tab, by clicking on the "Plus" next to the Consensus task to expand it and see details pertaining to the sub-tasks:
If a sub-task is in the "Archive" stage it means it has been completed and submitted.
If a sub-task has been assigned to a specific annotator, but you wish to unassign it from that person and place it back in the queue for that specific consensus sub-stage, you can click on the "Un-assign and send back to queue" button for that sub-task:
Once all sub-stages have been annotated, they will be archived and they will no longer be accessible through the "Tasks" tab. They will, however, be accessible from the "Stage History" panel in the labeling editor when opening the main task.
## Settings
### Stage Settings
#### Setup
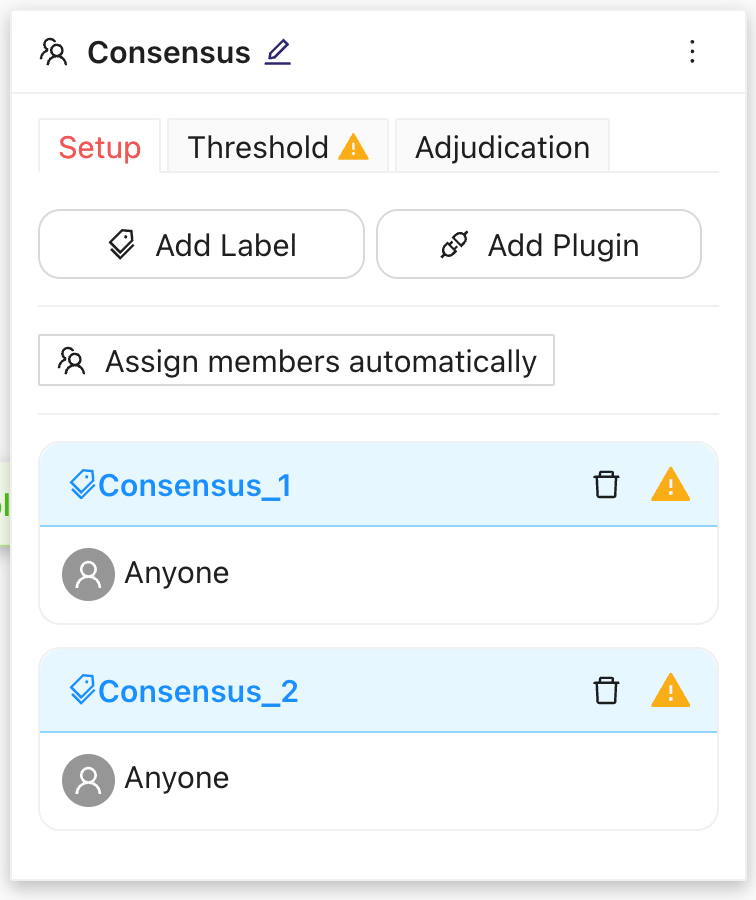
Clicking on *Add Label* will add a label stage. Clicking on *Add Plugin* will add a plugin stage. Click on each individual stage to change their options. Click on the trash can to delete the stage.
#### Assign members automatically
By default, Ango Hub does not prevent the same annotator from annotating the same asset more than once as part of a consensus stage.
For example, if you add two Label tasks which can be annotated by *Anyone*, like so:
Labeler A will open their labeling queue and go through the tasks in Consensus\_1.
If no other annotator has opened the tasks annotated by Labeler A, and Labeler A clicks on *Start Labeling* and enters the labeling queue, they may enter the Consensus\_2 queue and label the same tasks again. This way, consensus will not be calculated between two different annotators, as usually expected, since the same annotator will have annotated both tasks themselves.
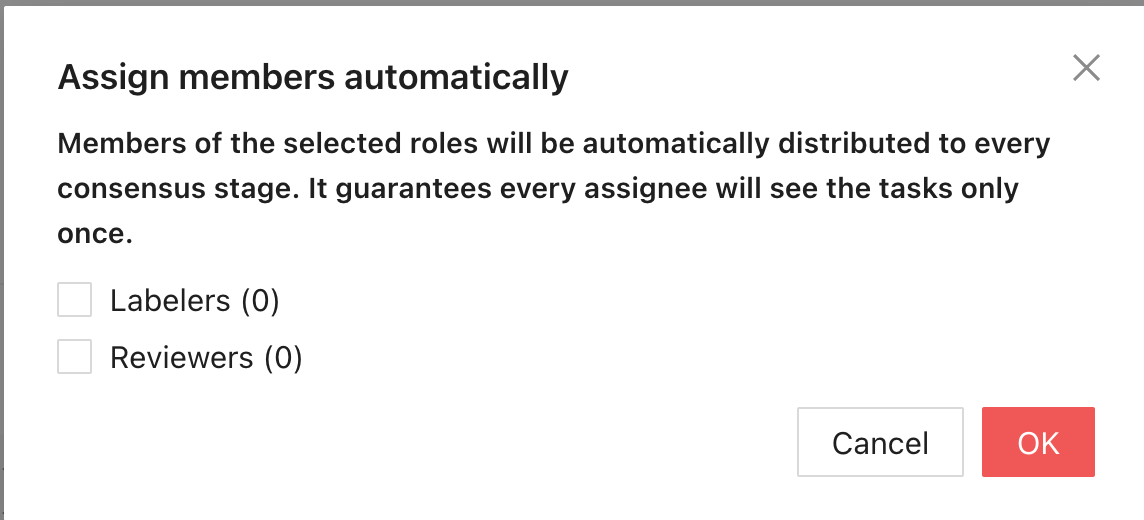
To prevent this, you'd have to assign each labeling stage in consensus to different annotators. *Assign members automatically* distributes project members across the Label sub-stages for you.
Select the Consensus stage in your project’s *Workflow* tab, open *Setup*, and click on *Assign members automatically*. In the dialog, select *Labelers*, *Reviewers*, or both, then click *OK*.
Members with the selected roles will be distributed across the Label sub-stages in the selected Consensus stage. Plugin sub-stages are not assigned members. If, after doing so, there are no consensus stages in your container assigned to *Anyone*, then you have guaranteed that no labeler will see the same task twice.
#### Threshold
From this view, you will be able to pick what will be determined as *Agreement* and *Disagreement*. You will see a list of labeling tools present in your project.
To have a tool or classification be used to decide whether the task goes to *Agreement* or *Disagreement*, enable the toggle next to it. Disabled items are not available for consensus thresholds.
In the example above, we have three tools: a bounding box named Vehicle, a radio classification named Color, and a single dropdown named Model. In this example, the task will be considered in agreement when at least 30% of the annotators give the same answer to Color, *and* at least 30% of annotators give the same answer to Model. When both of these conditions are satisfied, the task is marked as being in *Agreement.*
Since the "Vehicle" bounding box had its toggle turned off, annotations from that class will not be used to decide whether the task goes to *Agreement* or *Disagreement*.
{% hint style="info" %}
If no thresholds are selected, or if all selected thresholds are set to 0%, all tasks sent through the Consensus stage will go to *Agreement*.
{% endhint %}
#### Adjudication
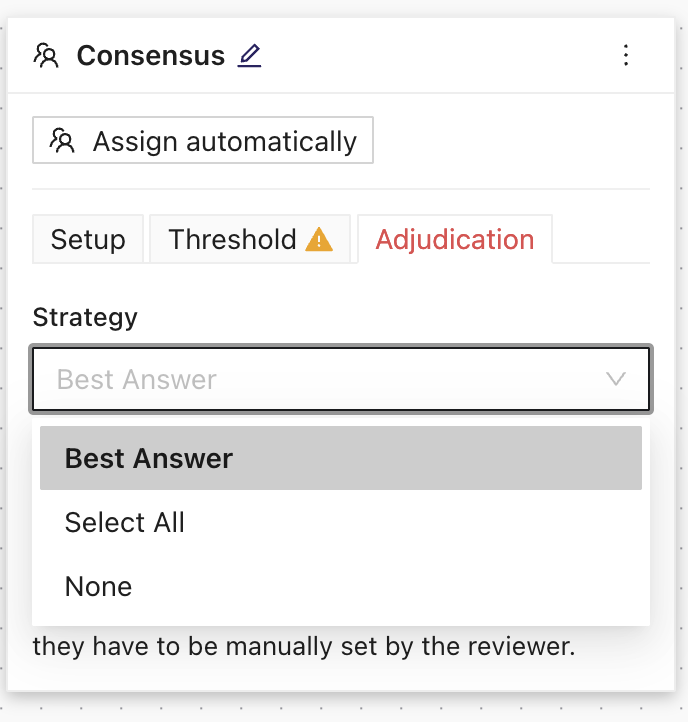
Scoring determines whether the task leaves through Agreement or Disagreement. Adjudication is a separate step which determines which annotations the output task contains. Changing the adjudication method does not change any consensus score or threshold result.
**Best Answer**
The output task contains the annotations from the highest-scoring submission for each class where consensus can be calculated. As a result, the output may be a composite assembled from several annotators rather than one annotator's complete answer.
* For example, if the consensus stage has three judgment sub-stages, and the task has three radio classifications A, B, and C, and one bounding box class D, the task output at the end will have, for each classification, the answer annotators coalesced on the most, and for class D, the bounding boxes created by the annotator with the highest class D consensus score.
* For classes where consensus cannot be calculated (e.g. assume in our project there is a rotated bounding box class E), the final task will have the non-calculable classes from the first user who has submitted them in the consensus stage.
* So in this case, we would have the best answers from classes A, B, and C, then the bounding boxes drawn by the user with the highest class D consensus score, and for class E, we would have the answers given by the first user to submit them in the consensus stage.
If two submissions have the same highest score for a class, Ango Hub uses the first of those submissions. Relations are not included in the output.
If, in the Consensus stage, some annotators did not create annotations using a certain class, or did not answer some classification answers, but others did, the output task will contain them, even if not all consensus annotators responded.
* For example, if we have a project with a bounding box class A, a polygon class B, a radio classification C, and a text classification D, assuming:
* User 1 only created 1 bounding box with class A, and answered the radio classification C (no other answers/annotations)
* User 2 only created 1 bounding box with class A, and a polygon with class B (no other answers/annotations)
* User 3 only created 1 bounding box with class A, answered the text classification D (no other answers/annotations)
* The output composite task will have:
* The class A bounding boxes drawn by the user with the highest class A consensus score
* The class B polygons created by User 2
* The class C radio answer from User 1
* The class D text answer from User 3
Here is a visual representation of the algorithm, given three annotators working on the same image:
**Select All**
The output task contains all tool and classification annotations from all consensus submissions, merged together. Duplicate annotations are not removed. Relations are not included.
Here is a visual representation of the algorithm, given three annotators working on the same image:
**None**
The output task contains no annotations. Use this option when the labeler or reviewer in the next stage should start with an empty editor instead of receiving a merged consensus answer.
The annotations created in the Consensus sub-stages remain available in the task's *Stage History*, where they can still be inspected. The adjudication method is applied when the task completes the Consensus stage; changing it later does not change tasks which have already completed the stage.
## How Consensus is Calculated
Consensus is calculated separately for each top-level, supported class in the project ontology. In this context, a *class* means one schema ID, such as the Bounding Box class `Vehicle` or the Radio classification `Weather`; it does not mean all Bounding Box or Radio classes combined.
All intermediate similarities use values from `0` to `1`, which Ango Hub displays as percentages from 0% to 100%.
### Pairwise comparison and missing answers
For each supported class, Ango Hub evaluates each consensus submission against every submission, including itself:
1. It compares the annotations from one submission with the annotations from each submission.
2. It averages the resulting pairwise similarities. This is that submission's score for the class.
3. It repeats the calculation with every submission as the starting submission.
4. The highest submission score becomes the final score for that class.
Self-comparison contributes to the score. For example, if two annotators give different non-empty Radio answers to the same question, each submission has one 100% self-comparison and one 0% comparison with the other submission. The final score for that class is therefore 50%.
Missing answers are handled as follows:
* If one submission contains an answer for a class and the other does not, their pairwise similarity is 0%.
* If neither submission contains an answer for the class, that comparison is ignored rather than treated as either agreement or disagreement.
* If nobody answers a class, no numeric score is produced for it. Its threshold is skipped, even when it is greater than 0%. An enabled consensus threshold does not require an annotation to exist.
### Classifications
For classifications with one value, answers are compared for exact equality. Radio, Checkbox, Boolean, Single-Select Dropdown, Single-Select Tree, Text, Slider, and File Upload Box answers normally receive either 100% for an identical value or 0% for a different value. Text comparison is case-sensitive and includes all characters and whitespace.
{% hint style="warning" %}
The built-in comparison currently scores an empty string, numeric `0`, or Boolean `false` as 0%, even when both annotators give the same answer. Two empty multi-select answers also score 0%. Avoid relying on consensus thresholds to recognize agreement on these values.
{% endhint %}
For Multi-Select Dropdown and Multi-Select Tree answers, Ango Hub uses the intersection over union of the selected answer sets:
`shared selections / all unique selections`
For example, the answers `[A, B]` and `[B, C]` share one selection out of three unique selections, so their pairwise similarity is 33.33%.
As a result of the pairwise averaging and highest-score steps, an exact-answer classification behaves like majority agreement. If three annotators answer `Cat`, `Cat`, and `Dog`, each `Cat` submission matches two of the three submissions, including itself. The final class score is 66.67%.
### Entities
For Entity annotations, Ango Hub compares spans belonging to the same Entity class. The similarity of two spans is:
`overlapping character positions / character positions covered by the combined span`
Identical spans receive 100%, partially overlapping spans receive a proportional partial score, and non-overlapping spans receive 0%.
### Points
For two Point annotations in the same class, Ango Hub compares their Euclidean distance (`d`) with the asset diagonal (`D`), where `D = √(width² + height²)`. For example, an image 1200 pixels wide and 500 pixels high has a diagonal of 1300 pixels.
Points at the same position, or no more than 0.1% of the diagonal apart, receive 100%. Between 0.1% and 100% of the diagonal, the score decreases linearly. Points separated by the full diagonal or farther receive 0%.
See the following visual examples:
### Bounding Boxes, Polygons, and multiple objects
Bounding Boxes and Polygons belonging to the same class are compared using an area-overlap score based on Intersection over Union (IoU). The built-in calculation adds 1 to the combined area in the denominator:
`overlapping area / (total area covered by either object + 1)`
Identical objects therefore score below 100%. For example, two identical 10 × 10 pixel boxes score approximately 99.01%. Partially overlapping objects receive a lower score, and non-overlapping objects receive 0%. A 100% threshold for these tools can reject visually identical annotations.
When two submissions contain multiple Entities, Points, Bounding Boxes, or Polygons of the same class, each annotation in the smaller set keeps its highest similarity against the annotations in the larger set. The same annotation in the larger set may be the best match for more than one annotation. When annotation counts differ, Ango Hub adds zero-valued penalties before averaging. This is not a unique one-to-one assignment, and the result should not be interpreted as the percentage of objects that match.
### Per-class, per-submission, and overall scores
Ango Hub records three related types of score:
* **Per-submission score for a class:** the average pairwise similarity between that submission and all submissions for one class.
* **Final score for a class:** the highest per-submission score achieved for that class. These scores are stored in the task's detailed consensus results and are used for thresholds.
* **Overall task consensus score:** the arithmetic mean of all numeric final class scores. Classes for which no numeric score was produced are omitted from this average.
For the score shown on an individual consensus submission in Stage History, Ango Hub first averages that submission's class scores within each supported annotation family, such as classifications, Entities, Bounding Boxes, Polygons, and Points. It then averages the numeric family scores. This may differ from the overall task consensus score, which directly averages the final per-class scores after taking the highest submission score for every class.
### Threshold evaluation
Thresholds are evaluated against the numeric final score for each selected class, not against the overall task consensus score. A single numeric class score below its enabled threshold sends the task through Disagreement. A score equal to its threshold passes.
Classes without a numeric score are skipped. This includes classes that nobody answered and annotation types excluded from scoring. A task can therefore leave through Agreement even when an enabled class has no annotations or no score.
If no thresholds are enabled, or if every enabled threshold is 0%, the task leaves through Agreement. Thresholds only control routing; the adjudication method controls the annotations included in the output task.
## Output
The Consensus stage has two outputs: *Agreement* and *Disagreement*.
If a numeric class score falls below its enabled threshold in the [stage setup](#threshold), the task leaves through *Disagreement*. Otherwise, it leaves through *Agreement*. Classes without a numeric score are skipped.
### The Output Task
The task you will get as the output will be determined by the method you pick in the stage's *Adjudication* tab. The task sent as output is not the judgment from a single annotator; it is a composite task.
---
# Agent Instructions
This documentation is published with GitBook. GitBook is the documentation platform designed so that both humans and AI agents can read, navigate, and reason over technical content effectively. Learn more at gitbook.com.
## Querying This Documentation
If you need additional information that is not directly available in this page, you can query the documentation by asking a question.
Perform an HTTP GET request on the following URL with the `ask` and `goal` query parameters:
```
GET https://docs.imerit.net/core-concepts/workflow/consensus.md?ask=&goal=
```
`ask` is the immediate question: it should be specific, self-contained, and written in natural language.
`goal` is what the user is ultimately trying to achieve, the reason they need the answer. Sharing it helps GitBook give you a better, more relevant answer. A goal is most helpful when it describes the outcome the user wants rather than restating the question. For example, with `ask=how do I create an API token`, a goal like `automate deployments from our CI pipeline` lets GitBook tailor the answer to that use case.
The response will contain a direct answer to the question and relevant excerpts and sources from the documentation.
Use this mechanism when the answer is not explicitly present in the current page, you need clarification or additional context, or you want to retrieve related documentation sections.